Contribute a verifiable environment. Help build post-training experiments and measure what generalizes across eight domains.
How we think
Every submission runs the same function. You control exactly one variable:
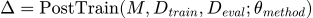
Training data
D_train is your entry, and the only term you control. It is a corpus of task packages: each one a task.md describing the goal and sandbox limits, a Docker environment that runs it, a verifier that scores attempts, and an oracle that proves the task is solvable. Everything else in the function is held fixed, so the leaderboard measures exactly how much your environments teach, and everything accepted is released openly for the community to build on.
The pipeline
- 01Contribute
A self-contained task package:
task.md, an environment, verifier, and oracle.task.md # prompt + limitsenvironment/Dockerfileverifier/├─ test.sh # writes reward├─ test_outputs.py├─ verifier.md└─ rubrics/verifier.mdoracle/solve.sh # must score 1.0 - 02Post-train
Train with a pinned recipe. Explore the completed Hugging Face experiment in the cookbook.
Reward · illustrative0.804- recipe
- SFT → GRPO
- step
- 2400
- lr
- 1e-6
- kl
- 1e-3
- batch
- 8
- max_tokens
- 4096
- 03Score
Check task-verifier results; measure transfer separately on held-out tasks.
Checks · illustrative - 04Rank
Ranked by held-out change: pass rate after training minus before, in the same run.
Leaderboard · illustrative- 01
 @xiangyi
- 02
 @xikron
- 03
 @bingranLi
- 04
 @suzy
- 05
 @user90107
- 01
Organizers
- Jiankai Sun
- Chujun Tao
- Yimin Liu +1
- Join the list →
 BenchFlow
 BenchFlow
 BenchFlow
 BenchFlow
 RLWRLD
 Amazon
 UC Berkeley
 Northwestern
 USC
 Moody's
 UC Berkeley
Call for contributions
Help build the environments, verifiers, and tools that make post-training useful.
FAQ
Anyone: researchers, engineers, students, and hobbyists. There's no affiliation requirement, and you can enter solo or as a team.
No GPUs. Authoring a task and checking it with scripts/check_task.py needs no key at all, and the oracle replay (scripts/run_local.sh) needs only Docker. The arena’s own validate, like submitting, needs a Hugging Face token: any valid one, since it only identifies you. Training runs on BenchFlow’s compute, and only a collection’s author or a BenchFlow editor can launch it.
A collection of 1 to 200 task packages. Each package is a task.md (YAML frontmatter + Markdown prompt), an environment/ Docker build, a verifier/ that scores attempts, and an oracle/ that proves the task is solvable. The full schema is in the spec.
Open the shared arena on Hugging Face, sign in with Hugging Face, and use Submit a collection with a pinned revision of a public Hugging Face dataset, which we recommend: a public GitHub repo works too, but every participant’s GitHub checks share one hourly GitHub limit, so a check can have to wait for the next hour. Or give your coding agent the arena’s agent instructions; it validates and submits with the headless CLI. First run scripts/check_task.py and scripts/run_local.sh from a clone of the posttrainarena repository, which also has the starting kit, so validation passes the first time. The full walkthrough is in the cookbook.
A challenge fixes the base model, the training recipe and a held-out suite. Each run evaluates the base model on that suite, trains it on your tasks, and evaluates it again: your score is the change, held-out pass rate after training minus before, in percentage points, measured in the same run. A BenchFlow editor reviews each result, and the leaderboard ranks collections by their mean change over accepted runs. Your tasks never include the suite's: validation refuses near-copies of them.
Everything accepted is released openly. The point is to grow the commons of high-quality, diverse RL environments, not to lock anything away.
Contributions are open now: you can check and submit collections on the arena. Runs are paused while the organizers fix the evaluation; the arena’s front page says whether a challenge takes runs, and why not. Competition dates aren’t announced yet.